
TL;DR:
- Storing file metadata and a path in the database is ideal for most cases, while file bytes suit smaller files with strict consistency needs. For large files or existing object storage, storing only the URI reduces backup size and complexity; report rows are suited for analytics and dashboards. Operational constraints like backup time, compliance, and access frequency guide the appropriate pattern choice, with automation tools simplifying scheduled delivery and error handling.
For most professional use cases, the best approach to save reports to a database is to store file metadata plus a path or object-storage reference rather than raw file bytes. That said, two other patterns are genuinely useful depending on your constraints:
- Store file bytes (BLOB/varbinary/bytea): Best when files are small to medium (under 10–50 MB), you need transactional consistency, or a single backup covers everything. Use
varbinary(max)in MSSQL,byteaor a Large Object (OID) in PostgreSQL, andLONGBLOBin MySQL. - Store path or URL only: Best for large files or when you already use object storage (S3, Azure Blob). The DB holds metadata; the file lives elsewhere. Backup size stays manageable.
- Persist report rows/aggregates to a reporting DB: Best for analytics, dashboards, and pre-aggregated data. No files involved. Queries run fast; the transactional DB stays clean.
Quick trade-off summary:
| Pattern | Backup impact | Access speed | Transactional | Best for |
|---|---|---|---|---|
| File bytes in DB | High | Fast (single query) | Yes | Audit archives, small PDFs |
| Path/URL reference | Low | Depends on storage | Partial | Large files, object storage |
| Report rows/aggregates | Medium | Very fast | Yes | Analytics, dashboards |
Table of Contents
- How do you choose between storing bytes, a path, or report rows?
- DDL and SQL examples for storing report files in MSSQL, PostgreSQL, and MySQL
- Practical code snippets: read bytes, insert, and retrieve
- How common reporting engines map to database storage
- How to run report generation and DB writes asynchronously
- Operational checklist for storing reports in a database
- When does a report automation tool make sense?
- Key Takeaways
- The pattern most teams get wrong
- Hands-free report delivery to your database, without custom code
- Useful sources
- FAQ
How do you choose between storing bytes, a path, or report rows?
The decision comes down to four constraints: file size, backup policy, access pattern, and compliance requirements.
File bytes in the database makes sense when you need atomic consistency between the file and its metadata, your files stay under roughly 50 MB each, and your DBA is comfortable with a larger backup set. Audit trails and compliance archives often land here because a single transaction either saves the report and its metadata or rolls back entirely.
Storing a path or URL is the right call when files are large, when you already have object storage, or when your backup window cannot absorb the extra size. The DB row holds the filename, MIME type, size, checksum, and the storage URI. The file lives in S3, Azure Blob, or a network share. Retrieval adds one extra hop, but backup and restore stay fast. Storing large volumes of PDFs or binary documents directly in a database can cause backup bloat and increased storage management complexity, which is why many teams prefer object storage and store only URIs in the DB for large files.
Persisting report rows is a separate pattern entirely. You are not storing a file at all. You are writing pre-aggregated or denormalized data into a read-optimized reporting database so that dashboards and ad hoc queries run without touching the transactional system.
Operational constraints to evaluate before you decide:
- Backup window: how long can a full backup run before it affects production?
- RTO/RPO: can you afford to restore a multi-hundred-GB database to recover one report?
- Compliance: does your policy require the file and its metadata to be atomically consistent?
- Search and indexing: do users need full-text search on report content? (Object storage + a search index is usually better.)
- Access frequency: reports retrieved daily warrant a different approach than annual audit archives.
DDL and SQL examples for storing report files in MSSQL, PostgreSQL, and MySQL
Good database schema design for report storage always separates metadata columns from the binary payload. Index the metadata; never index the binary column.
MSSQL with varbinary(max)
CREATE TABLE report_files (
    id            INT IDENTITY(1,1) PRIMARY KEY,
    filename      NVARCHAR(255)   NOT NULL,
    mimetype      NVARCHAR(100)   NOT NULL,
    file_size     BIGINT          NOT NULL,
    checksum      CHAR(64)        NOT NULL,  -- SHA-256 hex
    uploaded_at   DATETIME2       NOT NULL DEFAULT SYSUTCDATETIME(),
    report_data   VARBINARY(MAX)  NOT NULL
);
Parameterized INSERT (avoid inline literals to prevent injection):
INSERT INTO report_files (filename, mimetype, file_size, checksum, report_data)
VALUES (@filename, @mimetype, @fileSize, @checksum, @reportData);
PostgreSQL with bytea
CREATE TABLE report_files (
    id            SERIAL PRIMARY KEY,
    filename      TEXT            NOT NULL,
    mimetype      TEXT            NOT NULL,
    file_size     BIGINT          NOT NULL,
    checksum      CHAR(64)        NOT NULL,
    uploaded_at   TIMESTAMPTZ     NOT NULL DEFAULT NOW(),
    report_data   BYTEA           NOT NULL
);
For files larger than a few MB, consider the Large Object (OID) pattern instead. Store the OID in a BIGINT column and use lo_import / lo_export. PostgreSQL's bytea is simpler for most cases, but large objects have different behaviors for permissions and lifecycle cleanup that require explicit vacuumlo maintenance.
MySQL with LONGBLOB
CREATE TABLE report_files (
    id            INT UNSIGNED AUTO_INCREMENT PRIMARY KEY,
    filename      VARCHAR(255)    NOT NULL,
    mimetype      VARCHAR(100)    NOT NULL,
    file_size     BIGINT UNSIGNED NOT NULL,
    checksum      CHAR(64)        NOT NULL,
    uploaded_at   DATETIME        NOT NULL DEFAULT UTC_TIMESTAMP(),
    report_data   LONGBLOB        NOT NULL
);
MySQL requires max_allowed_packet to be set high enough to accept the full binary payload. A common starting point is 64M; increase it only as far as your largest expected file. Use BLOB for files under 65 KB and MEDIUMBLOB for files under 16 MB.
Pro Tip: Always store file_size and a SHA-256 checksum alongside the binary column. On retrieval, recompute the checksum and compare before serving the file. This catches silent corruption without a full file scan.
Practical code snippets: read bytes, insert, and retrieve
C# with MSSQL
byte[] reportBytes = File.ReadAllBytes(filePath);
string checksum = ComputeSha256(reportBytes);

using var cmd = new SqlCommand(insertSql, connection);
cmd.Parameters.Add("@filename",   SqlDbType.NVarChar).Value = fileName;
cmd.Parameters.Add("@mimetype",   SqlDbType.NVarChar).Value = "application/pdf";
cmd.Parameters.Add("@fileSize",   SqlDbType.BigInt).Value   = reportBytes.Length;
cmd.Parameters.Add("@checksum",   SqlDbType.Char).Value     = checksum;
cmd.Parameters.Add("@reportData", SqlDbType.VarBinary).Value = reportBytes;
await cmd.ExecuteNonQueryAsync();
To serve the file back, read the VARBINARY(MAX) column into a byte array and write it to the HTTP response with the stored MIME type.
Python with psycopg2 (PostgreSQL bytea)
with open(file_path, "rb") as f:
    data = f.read()

cur.execute(
    "INSERT INTO report_files (filename, mimetype, file_size, checksum, report_data) "
    "VALUES (%s, %s, %s, %s, %s)",
    (filename, "application/pdf", len(data), sha256(data), psycopg2.Binary(data))
)
conn.commit()
psycopg2.Binary wraps the bytes so the driver handles escaping correctly. For Large Objects, use conn.lobject() instead and store the returned OID.
Node.js with MySQL2
const data = fs.readFileSync(filePath);
await connection.execute(
  `INSERT INTO report_files (filename, mimetype, file_size, checksum, report_data)
   VALUES (?, ?, ?, ?, ?)`,
  [filename, "application/pdf", data.length, sha256hex(data), data]
);
The mysql2 driver accepts a Buffer directly for LONGBLOB columns. For the mssql npm package, pass the Buffer as a VarBinary parameter.
Memory warning: loading a 200 MB report into a single Buffer or byte array will exhaust memory on a small server. For files over roughly 50 MB, use streaming inserts or chunked writes rather than readFileSync / ReadAllBytes.
- Use parameterized queries on every insert and select. String-concatenated SQL with binary data breaks drivers and opens injection vectors.
- Wrap insert and metadata update in a single transaction so a partial write never leaves an orphaned row.
- For SSRS, the practical approach is to export to a temp file first, then read that file's bytes and insert them into the DB in a follow-up step.
Pro Tip: For files over 50 MB, switch to the path/URL pattern instead of fighting with packet limits and memory. The code is simpler and the operational story is much cleaner.
How common reporting engines map to database storage
SSRS
SSRS does not write directly to a custom table. The standard approach: configure a subscription to export to a file share, then run a background job (SQL Agent, PowerShell, or a .NET worker) that reads the exported file, computes a checksum, and inserts the bytes or path into your report_files table. The community-recommended pattern is export to temp file, then insert bytes.
DevExpress XtraReports
DevExpress provides a ReportStorageWebExtension that you implement to persist report layouts. The End-User Report Designer stores LayoutData as varbinary in a SQL Server table. Override SetData to write and GetData to read. This stores the layout (the template), not the rendered output. Keep a separate table for rendered output snapshots.
Crystal Reports
Crystal Reports exports to PDF, Excel, or other formats via the ReportDocument.ExportToStream method. Capture that stream, convert to a byte array, and insert using the MSSQL or MySQL DDL shown above. Store the .rpt layout file separately if you need to re-run the report with new data. For automating Crystal Reports exports on a schedule, a dedicated scheduler removes the manual step entirely.
Power BI
Power BI reports are published artifacts. For database storage, the practical path is to export a rendered PDF or Excel snapshot via the Power BI REST API, then insert the file bytes or store the path. For sharing a static Power BI report as PDF, the export step is straightforward; the DB insert follows the same pattern as any other file. Alternatively, write the underlying data to a reporting DB and let Power BI query that instead of the transactional source.
Ignition (Inductive Automation)
Ignition's file-in-database example uses a LongBlob or varbinary column and renders the stored bytes in a client-side PDF Viewer component. The pattern is read file bytes, insert into the binary column, then query and pass the bytes to the viewer.
Per-engine implementation steps:
- SSRS: subscription → temp file → background job → insert bytes or path
- DevExpress: implement
ReportStorageWebExtension→ overrideSetData/GetData→varbinarycolumn - Crystal Reports:
ExportToStream→ byte array → parameterized insert - Power BI: REST API export → file bytes or path → insert or store reference
- Ignition: read file →
LongBlob/varbinaryinsert → PDF Viewer component
How to run report generation and DB writes asynchronously
Move heavy report generation to background jobs. Generating a large report synchronously inside an HTTP request will time out, block threads, and frustrate users. The fix is a queue.
- User or scheduler triggers a report request. The API writes a job record to a queue (RabbitMQ, AWS SQS, or a simple DB-backed job table) and returns immediately with a job ID.
- A worker process picks up the job, generates the report, and writes the output (bytes or path) to the database.
- On completion, the worker updates the job record status and sends a notification (email, Slack, or Microsoft Teams message) with a direct link or DB reference.
- On failure, the worker retries with exponential backoff. Use a run ID or dedup key on the insert so a retry does not create duplicate rows.
- After a configurable number of retries, move the job to a dead-letter queue and alert the on-call engineer.
Key operational points:
- Assign each report run a unique
run_idbefore the job starts. Use it as an idempotency key on the DB insert. - For large files, stream the report output directly to object storage and write only the path to the DB. Never buffer a 200 MB file in a worker's memory.
- Monitor queue depth, worker processing time, and failure rates. A growing queue or rising failure rate usually signals a slow query in the report or a DB connection bottleneck.
- Automating and scheduling report generation with a dedicated BI tool handles most of this plumbing out of the box.
Operational checklist for storing reports in a database
Security controls:
- Grant the application DB account only
INSERT,SELECT, andUPDATEon the report tables. NoDROP, noTRUNCATE. - Encrypt data at rest (TDE in MSSQL,
pgcryptoor filesystem encryption in PostgreSQL) and enforce TLS for all connections. - Audit access to report tables, especially for compliance-sensitive content.
Backups and restore impact:
- A database holding gigabytes of binary report files takes significantly longer to back up and restore than a metadata-only database. Test your RTO before you commit to the bytes-in-DB pattern at scale.
- Consider a tiered strategy: keep recent reports (last 90 days) in the DB for fast access; archive older files to object storage and store only the path in the DB row.
- PostgreSQL Large Objects require
vacuumloto clean up orphaned OIDs after deletes. Skipping this step causes storage to grow silently.
Retention policies:
- Define a retention schedule in the schema (add a
retain_untilcolumn) and run a nightly cleanup job that deletes or archives expired rows. - Partition large tables by
uploaded_atmonth so you can drop old partitions without a full-table delete.
Indexing:
- Index
filename,uploaded_at,mimetype, and any foreign keys. Never create an index on aVARBINARY,BYTEA, orBLOBcolumn.
Capacity planning:
- Estimate average file size times expected monthly report volume to project storage growth. Set alerts at 70% and 90% of available storage. For financial report delivery, retention requirements can push storage into the hundreds of gigabytes quickly if file bytes are stored directly.
When does a report automation tool make sense?
Automation tools earn their keep when you need reliable, hands-free scheduling, delivery to multiple destinations (database, email, file shares, cloud storage), and error handling that does not require an engineer on call at 2 AM.
Feature checklist for evaluating automation tools:
- Native DB destinations (write directly to a table or stored procedure)
- Retry logic and alerting on failure
- Templated exports to PDF and Excel
- Dynamic, data-driven scheduling (run when a condition is met, not just on a clock)
- Audit trail of every run, output, and delivery
- REST API or webhook integration for triggering runs from external systems
ChristianSteven Software's products map directly to these needs. PBRS for Power BI handles automated Power BI exports including delivery to database destinations. ATRS covers Tableau scheduling with the same delivery options. CRD (Crystal Reports Scheduler) handles Crystal Reports export and delivery, including DB writes, without custom code. All three carry SOC 2 Type II certification, which matters when auditors ask how report delivery is controlled.
For teams evaluating any automation tool: run a trial with a real workflow (schedule a report, export to PDF, insert into a DB table, trigger a failure, and verify the retry and alert). If the tool cannot demonstrate clean failure recovery and an audit log in a 30-minute trial, it will not hold up in production.
Pro Tip: Store report definitions (the template, parameters, and schedule) separately from report outputs (the rendered file or rows). They have different retention needs, different access patterns, and different security requirements. Mixing them in one table creates operational debt fast.
Key Takeaways
Storing metadata plus a file reference is the right default for most teams; store file bytes only when transactional consistency or a single-backup requirement justifies the operational cost.
| Point | Details |
|---|---|
| Choose the right pattern first | Match your pattern (bytes, path, or rows) to file size, backup policy, and compliance needs before writing any DDL. |
| Use correct column types | MSSQL uses varbinary(max), PostgreSQL uses bytea or Large Object, and MySQL uses LONGBLOB with max_allowed_packet tuned. |
| Always run async | Move report generation to background workers with a run ID for idempotency; never generate large reports inside an HTTP request. |
| Index metadata, not binaries | Index filename, uploaded_at, and foreign keys; never index VARBINARY, BYTEA, or BLOB columns. |
| ChristianSteven Software automates delivery | PBRS, ATRS, and CRD handle scheduling, export, DB delivery, retry, and audit trail without custom code. |
The pattern most teams get wrong
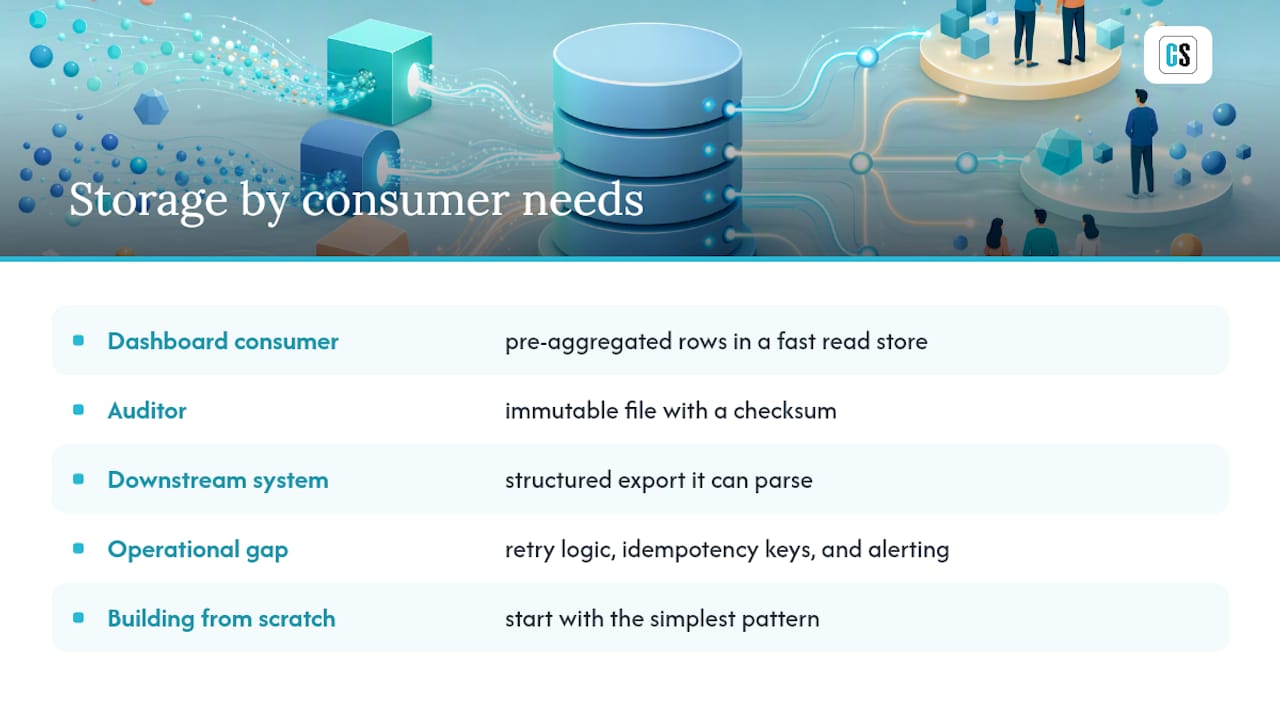
Most engineers I see approach report persistence by asking "where should I put the file?" That is the wrong starting question. The right question is "what does the consumer of this data actually need?" A dashboard consumer needs pre-aggregated rows in a fast read store. An auditor needs an immutable file with a checksum. A downstream system needs a structured export it can parse. Each answer points to a different pattern, and conflating them is what creates the bloated, slow databases full of gigabytes of PDFs that nobody can query.
The other thing teams consistently underestimate is the operational gap between "it works in dev" and "it works at 3 AM when the nightly batch fails." Retry logic, idempotency keys, and alerting are not nice-to-haves. They are the difference between a system your team trusts and one they babysit. ChristianSteven Software's SOC 2 Type II certification is a signal worth noting here: it means the audit trail and access controls have been independently verified, which is exactly what you need when a regulator asks who accessed which report and when.
If you are building this from scratch, start with the simplest pattern that satisfies your actual requirements. Add complexity only when a real constraint forces it.
Hands-free report delivery to your database, without custom code
Writing your own scheduler, retry logic, and DB insert pipeline is doable. It is also weeks of engineering time that does not differentiate your product. ChristianSteven Software's automation suite handles the entire pipeline: schedule a report, export it to PDF or Excel, deliver it to a database destination, retry on failure, and log every run to an audit trail.
PBRS for Power BI, ATRS for Tableau, and the Crystal Reports Scheduler each support database destinations natively. You configure the destination, set the schedule, and the tool handles the rest, including failure alerts and delivery confirmation. SOC 2 Type II certified, on-premises, and built for the reporting environments your team already uses.
Start a free trial or request a demo to see the DB delivery workflow running against your own reports.
Useful sources
- Reporting Database
- Reporting Database Pattern. One of the most common tasks on any… | by iamprovidence | Medium
- Storing Files in a Database | Ignition User Manual
- How to Store PDF or Document Files in a Database: Concepts and Techniques for MySQL, PostgreSQL, and MongoDB - NextStruggle - AskDushyant
- Custom Report Storage | .NET Reporting Tools | DevExpress Documentation
- Store SSRS Report export directly to database
- How can I store a PDF in PostgreSQL?
- Meita reports-generator (GitHub)
FAQ
Why use a database instead of a file system for report storage?
A database gives you transactional consistency, centralized access control, and a single backup target. It is the right choice when you need the file and its metadata to be atomically consistent or when compliance requires a tamper-evident audit trail.
How do I store a PDF in a database?
Read the file as bytes, then insert using a parameterized query into a VARBINARY(MAX) column (MSSQL), BYTEA column (PostgreSQL), or LONGBLOB column (MySQL). Always store the filename, MIME type, file size, and a SHA-256 checksum alongside the binary data.
Which database is best for storing reports?
MSSQL, PostgreSQL, and MySQL all handle binary report storage well. MSSQL's varbinary(max) is the most straightforward for .NET shops; PostgreSQL's bytea suits Linux-based stacks; MySQL's LONGBLOB works for PHP and Node.js environments. The choice usually follows your existing stack, not the storage feature.
When should I store a file path instead of file bytes?
Store a path or object-storage URI when files exceed roughly 50 MB, when backup size is a constraint, or when you already use S3 or Azure Blob. The DB row holds metadata and the URI; the binary stays in object storage.
Can ChristianSteven Software deliver reports directly to a database?
Yes. PBRS for Power BI, ATRS for Tableau, and CRD for Crystal Reports all support database destinations natively, handling scheduling, export, delivery, retry, and audit logging without custom code.